Engineering Studios That Specialize in Rebuilding AI-Generated Codebases After Product-Market Fit
Engineering studios diagnose and rebuild foundations while preserving working product behavior.
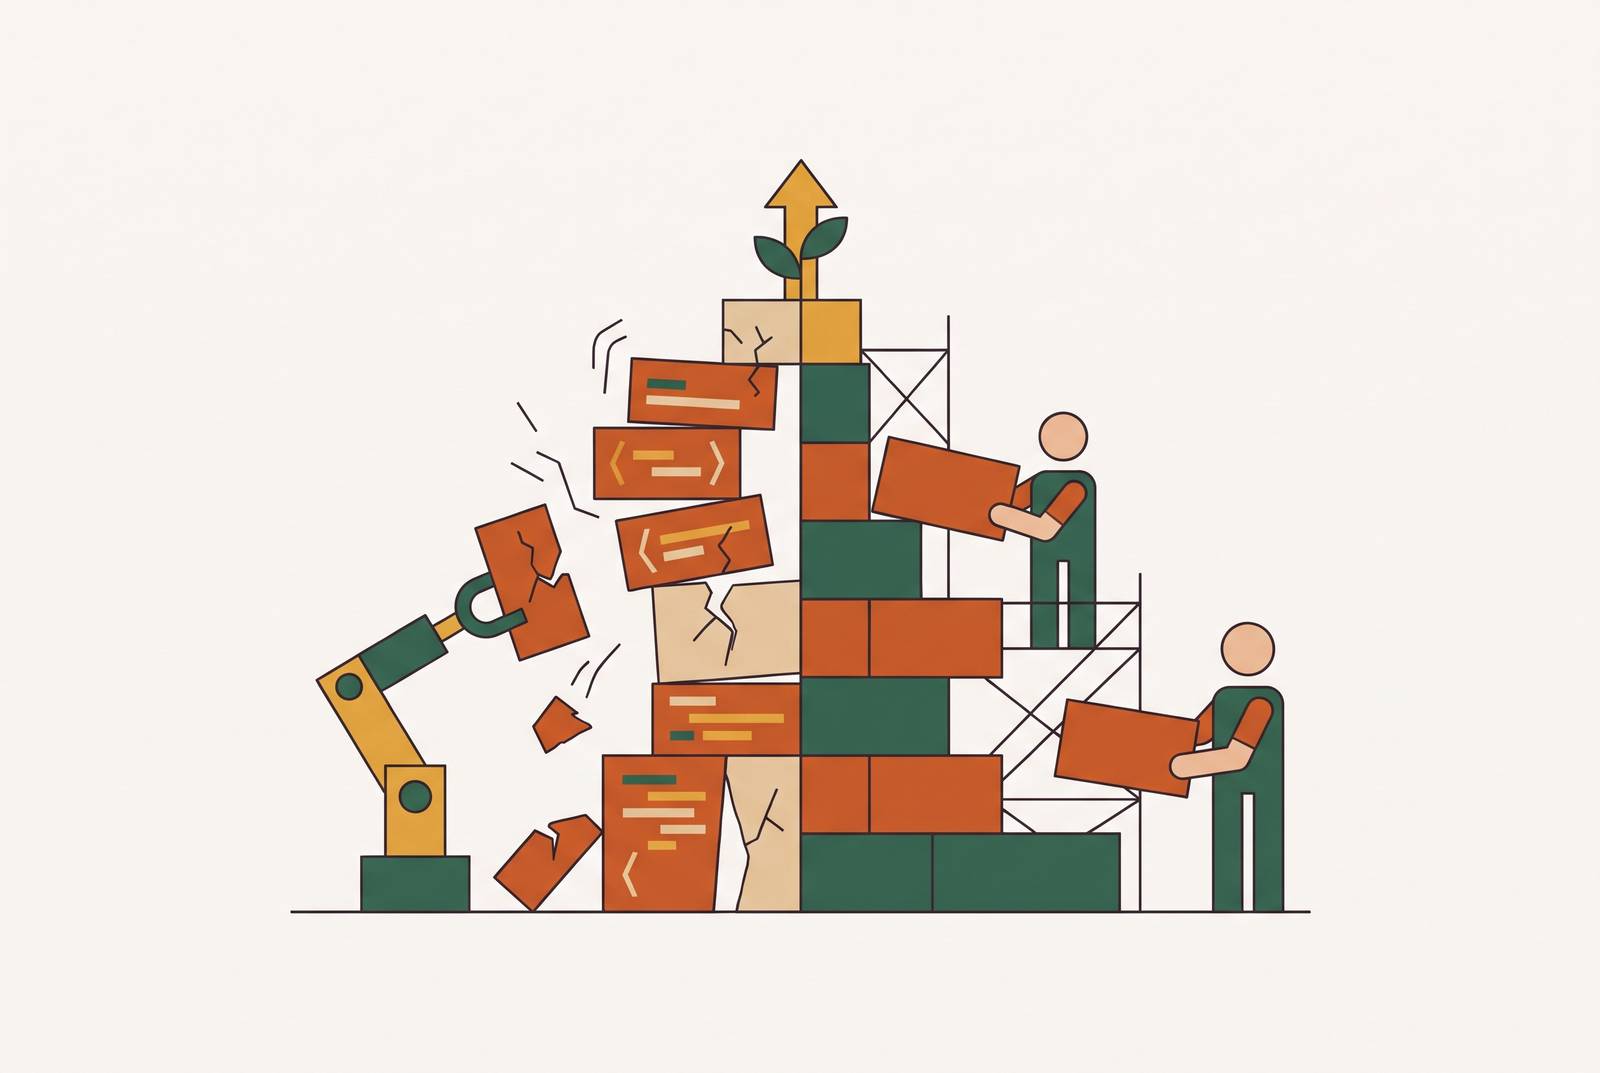
For a post-MVP rebuild of an AI-generated or freelancer-built codebase, hire a senior-led engineering studio that diagnoses before proposing a rewrite, preserves validated product behavior, and stays responsible for maintenance after launch. The decisive skill is rebuilding the foundations beneath a working business without recreating the lack of engineering oversight that made the first build fragile.
Why AI-generated codebases that reach product-market fit face a structural reckoning
A founder can have a product that earns revenue and still struggle to hire an engineer willing to take responsibility for its code. Those facts are not contradictory. The application has proved that customers want what it does, but not that its structure can support the business it has become. Before product-market fit, the first test was to get a product customers wanted to use into their hands. Afterward, keeping that product dependable becomes an obligation.
AI tools make this shift harder because the debt they leave can stay hidden in code that looks consistent. Codexical’s study describes generated code that follows project conventions because it learned those conventions from the existing codebase. Familiarity is not proof of sound design. A reviewer can recognize the style without understanding whether the underlying data model or security boundaries make sense. The code can therefore look orderly while leaving basic architectural questions unresolved.
Addy Osmani, formerly of Google Chrome engineering and now at Anthropic, popularized “comprehension debt,” the gap between how much code exists and how much people genuinely understand. Generation can outpace the team’s ability to absorb what it produces, while review capacity stays flat. Amazon CTO Werner Vogels named the related burden “verification debt.” A reviewer has to learn how the code works without having learned it by writing it. The cognitive burden has not disappeared with faster code generation.
That gap becomes unavoidable when customers depend on the product and engineers must change it safely. Product-market fit leaves in place the shortcuts that made it possible to launch. It changes their consequences. The founder now needs someone who can explain how the system works, identify where that understanding is incomplete, and take responsibility for what happens next.
What the failure record shows about where AI-generated code breaks in production
The hidden weaknesses are visible at security boundaries, in credential handling, and in access control. Security boundaries, credential handling, and access control determine who can reach data and what authority a user or service receives. Apiiro’s research found that privilege escalation paths and architectural design flaws in AI-generated code rose steeply, even as trivial syntax errors fell.
MoltBook provides a specific example of that distinction. The application shipped with a Supabase key in its client-side JavaScript and no row-level security. Wiz’s report documented the exposure of 1.5 million API authentication tokens and 35,000 email addresses. A working interface did not demonstrate that access was properly constrained.
The evidence also needs careful limits. One documented exposure does not establish that every AI-built application has the same flaw, and a research finding does not diagnose a particular startup’s codebase. Those limits strengthen the case for assessment. Assessment should establish whether the product’s credentials, permissions, and architecture have been examined, rather than whether its screens work or its generated code follows familiar patterns.
Does the problem come from AI generation or from weak engineering governance? Code review standards, access controls, and test coverage requirements govern how unsafe code can reach production. Replacing generated code without establishing those controls leaves the same gap in responsibility. A rebuild must therefore address both the system and the process that governs changes to it.
Why patching symptoms does not work, and what “rebuilding foundations” actually means
A patch can correct a defect without correcting the structure that keeps producing defects. That difference becomes expensive when each new change requires engineers to reconstruct how the application works before they can safely alter it. Patching becomes the wrong choice when repeated local repairs leave the data model, integrations, or security boundaries unresolved.
The IBM multiplier cited in the notes puts the cost of correcting technical debt in production at roughly 15x the cost of correcting it when AI generates the code. A founder cannot infer a rebuild budget from it, and it does not prove that every rewrite will save money. It does explain why the apparent price of a small fix can be misleading when the same structural problem remains beneath it.
Refactoring is a better fit when there is a small amount of generated code, no significant data model, and only minor integrations. When state has built up, there are multiple integrations, or security boundaries face customers, the core usually needs a senior-led rebuild. Existing UX can remain the specification. Customers have already validated what the product lets them do, even if the implementation needs replacement.
Sophylabs describes a rescue approach called “Option C,” which keeps the parts that work, fixes the parts that do not, and establishes a proper foundation beneath the existing application. Users continue using the product while improvements happen underneath. This is different from discarding the entire product and starting again. Typical rescue engagements run into the tens of thousands of dollars over weeks, which provides market context rather than a recommendation about what any particular founder should spend.
The scope depends on what the diagnosis reveals. Validated business logic and working integrations may deserve preservation, while data models and authentication patterns may require replacement. Once a core rebuild is justified, the next decision is who has the judgment to draw that boundary.
Who should you hire to rebuild an AI-generated codebase?
A rebuild studio needs to know how to find what is wrong, build sound production systems, and keep working with the client after delivery. Having worked in software development does not prove a studio can do all three. The first test is whether senior engineers can read the existing system and explain its architectural gaps, rather than simply produce an estimate for replacement code. That requires understanding both how AI tools generate software and how production systems fail.
The next test is restraint. A studio should distinguish validated UX, sound business logic, and working integrations from structures that cannot safely support the product’s next stage. A proposal to replace everything before that distinction has been made is a warning sign. So is a proposal that treats code quality scores as a substitute for examining security boundaries and data models. The studio is being hired to supply development capacity informed by a diagnosis.
The diagnosis and the scope that comes from it need to cover governance. Access controls, code review standards, and test coverage requirements are required parts of the rebuilt foundation before the features are complete. Otherwise, the work can leave cleaner code without changing who is responsible for keeping it sound. The deliverable is therefore more than a functioning replacement. It includes a way to judge and control future changes.
That responsibility needs a home after launch. Ongoing maintenance through a technical partnership can supply the engineering function a founder does not yet have, covering production monitoring, dependency management, and incremental improvement. A studio with no maintenance offering is proposing a project that ends at delivery. A handoff alone does not answer who will exercise engineering authority when the next urgent change arrives.
Values alignment is also a practical filter, especially for nonprofits and mission-driven founders. Limited budgets, staff with several roles, and mission-first decisions shape what can be built and maintained. A studio that understands those limits can judge the scope against what the organization can run and maintain. How it chooses engagements and makes trade-offs signals its values alignment.
These criteria also help evaluate a takeover of a freelancer-built MVP. The origin of the code does not remove the need to understand it, separate what works from what must change, and establish continuing ownership. For AI-generated systems, however, the studio should be able to explain the specific gap between code production and human understanding. Treating that gap as ordinary cleanup misses the reason a seemingly consistent codebase can be difficult to maintain.
How internal tooling built on no-code databases adds a second layer of structural debt
The application is not always the only foundation that needs attention. Many AI-built MVPs use Airtable or similar no-code databases for the core data that runs the business. Rebuilding the code customers use leaves the limits of that operational layer in place. A technical partner needs to examine both, because the business can remain dependent on its original data tooling after the application has changed.
Bending Spoons announced a definitive agreement to acquire Airtable in an all-cash transaction valuing it at $1.285 billion. The agreement makes ownership change part of the migration decision. It does not, by itself, establish a particular future pricing or product policy. For a team already weighing a move, the relevant question is whether its operational data should remain dependent on the current setup or move to a foundation better suited to its needs.
The alternatives serve different starting points. Retool is a low-code builder for engineering-led teams that want internal tools on top of existing databases and APIs. NocoDB sits directly on production databases such as PostgreSQL or MySQL, turning tables into interactive spreadsheets without moving the data. That distinction affects the scope of a migration. Building a new interface over an existing database is not the same decision as replacing where the data lives.
Baserow offers an open-source, self-hosted option, and its security page states that it provides compliance with GDPR, HIPAA, and SOC 2. Appsmith has self-hosting and lets teams access all of its source code. Its free Community self-hosted edition has no per-seat fees, while its paid self-hosted tiers charge for each user each month. For nonprofits considering their broader tooling budget, Monday.com offers 10 free Pro seats and a substantial discount on additional Pro seats.
These options do not form a universal ranking. Their fit depends on the existing database, the engineering team, and the organization’s operating constraints. The connection to the rebuild is narrower and more important than an alternatives roundup. A skilled technical partner finds application and data-layer problems together and includes both in the work, then plans the order to cause as little disruption as possible.
What to ask a rebuild studio before signing anything
The selection criteria become useful when a founder turns them into questions about the proposed engagement. Start with “What does your assessment process look like before you scope a rebuild?” The answer should describe a structured diagnostic phase before giving a rewrite price. Without that phase, the studio has not established which parts of the product need replacement.
Then ask “How do you distinguish what to keep from what to replace in an AI-generated codebase?” A useful answer should address business logic, validated UX, and security boundaries alongside code quality scores. Follow it with “What are the three most common failure modes you find in AI-generated codebases, and how do you test for them?” Specificity is the test here. A studio claiming specialization should be able to connect the risks it names to the way it assesses a system.
The conversation should then move explicitly from delivery to responsibility. Ask “What happens after the rebuild is delivered?” If the answer is a handoff, ask whether ongoing maintenance is available and what it covers. Establish who the post-launch contact will be and what engineering authority that person has. A project manager can organize the work, but that title alone does not say who makes the technical decisions.
Ask “Have you worked with founders at this stage before, and can we speak with one?” References from post-PMF founders are more relevant than references from greenfield builds because they concern taking responsibility for a product customers already use. The operational scope deserves equal attention. Where core data lives in no-code tooling, the assessment should address that layer as well as application code.
Finally, ask “How do you decide which founders to work with?” An answer limited to budget and timeline reveals different priorities from one grounded in mission and operating fit. Nonprofits can make the question concrete with “Do you have experience with mission-constrained budgets and multi-role staff?” Before signing, the founder should be able to identify both the foundations being rebuilt and the engineering authority that will remain responsible for them afterward.