Why GTM Stalls When Founders Double as the On-Call Engineer
Founders stuck on incident duty lose the sales momentum they need.
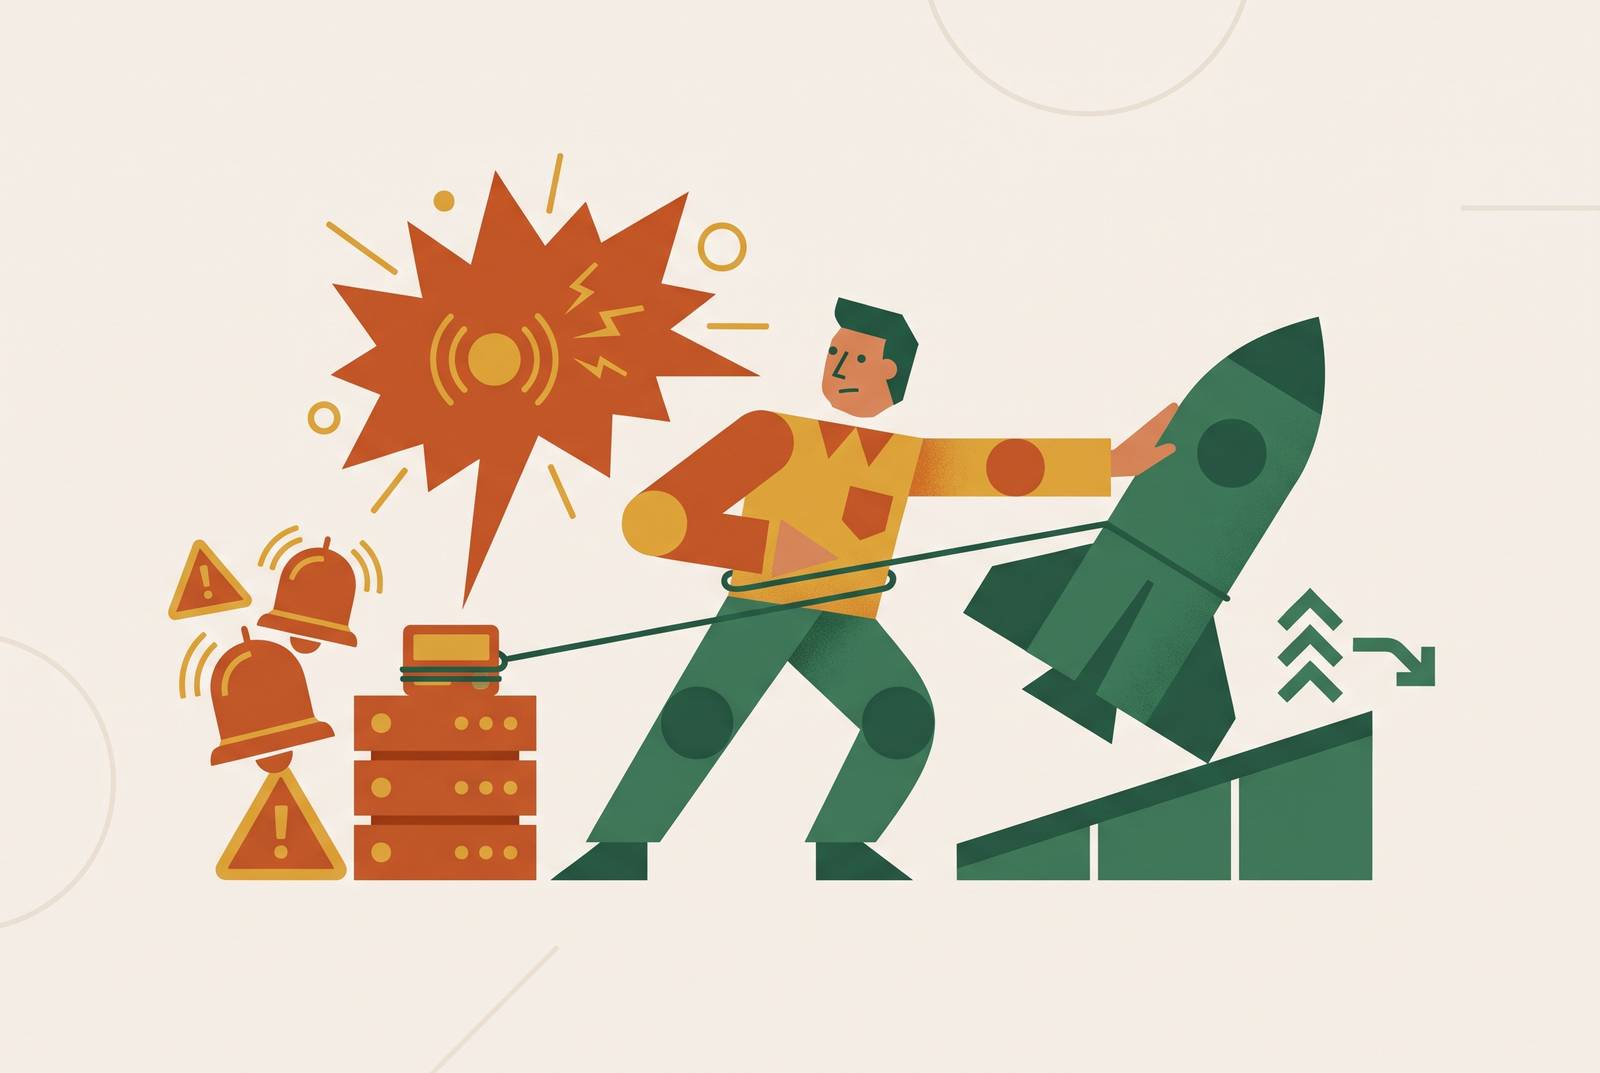
An ongoing engineering retainer is a long-term arrangement in which an engineering partner stays responsible for maintenance and support after launch, rather than leaving the founder to handle production problems. For non-technical founders, it provides continuing engineering support without a full-time hire. Go-to-market stalls when the person responsible for winning customers is also the only person who can keep the product running.
The structural problem: why the founder who built the product becomes its permanent hostage
The architecture creates the dependency before the calendar reveals it. An MVP is built for speed, and the founder who made its early trade-offs is often the only person who can safely change it. Once real users arrive, new features are built on those shortcuts. Each addition deepens the dependency on the person who understands the original structure. The founder becomes a single point of failure in engineering and acquisition at the same time.
In the MVP-to-production trap, the product has crossed into ongoing use, but its engineering model still assumes that its creator will be available whenever something breaks. Why does the role not shrink as the company grows? Because as the company grows, it asks more of the structure already in place while keeping that structure. The founder becomes harder to remove from engineering just as selling requires more attention.
Stripe described its Charges and Tokens APIs as foundational because they came first, despite their unsuitability as an abstraction for global payments. That architecture made other payment methods much harder to integrate and required a years-long overhaul. The example illustrates how Stripe’s early architecture constrained later development. A foundation suited to the first product can become an obstacle to the next one.
What the on-call founder is actually giving up while handling incidents
The work displaced by an incident is not interchangeable with whatever fits into the next free hour. Founder-led sales depends on trust-building, positioning judgment, and early-deal conversations that develop over time. A founder can return to a task after fixing production, but returning to a relationship is not the same as resuming work where it stopped. The opportunity cost is the momentum that never forms.
This is especially difficult for founders without an existing audience or a strong network. Their acquisition work begins without the distribution advantages that make some founders’ accounts of early growth look straightforward. Early sales can also obscure that gap. Customers who know the founder may put up with rough edges that buyers who know them less well will not. Treating those deals as proof of a repeatable sales motion leaves the founder with an unanswered question about why the next customer should buy.
Answering that question takes judgment that interruptions make harder to exercise. Underpricing, leaving distribution until later, and confusing developer interest with buying intent are not merely unfinished tasks. They shape the direction of subsequent work. A product-led or community-led top of funnel can support founder-led sales, but outbound belongs later, once a repeatable motion has been proven. Establishing that sequence requires attention to how interest becomes a purchase.
How the stall pattern develops: from slow sprints to a frozen pipeline
Users return, the MVP does its basic job, and there is no single failure that demands a new approach. Yet every change feels riskier than the last. Updates take longer, and small mistakes affect more than the feature being changed. Because the product is not visibly broken, slower delivery can look like an ordinary cost of growing.
Debt accumulates, sprint velocity drops, and a fix in one place breaks an adjacent feature. New developers take longer to become productive in the codebase. The founder is still the person who can deal with an incident fastest. Turning to that person is understandable each time, but the repeated choice prevents the team from developing an engineering function that can operate without them.
By the time the effect reaches the pipeline, it looks like a sales problem. Prospecting has no sustained rhythm, follow-ups lapse, and early relationships lose momentum because the founder’s calendar is organized around incidents. The transition is easy to miss. The product is still “working” by the minimum viable standard, even while the organization cannot give acquisition the attention it requires. What looks like weak demand may therefore be inseparable from the company’s inability to pursue demand consistently.
Eventually, local fixes can stop being enough. One founder who built their own automation reached a re-platforming wall at a critical ARR milestone because the separate optimizations could not form a coherent architecture. The system had to be torn down and rebuilt from scratch. At Series A, unmanaged debt can also surface during investor due diligence through slower teams, higher costs, and difficulty scaling. By then, a dependency that once looked internal has become visible to outsiders.
Why nonprofits experience this trap in a more compressed and harder-to-escape form
For a nonprofit, postponing infrastructure spending can feel like protecting the mission. Budgets are limited, staff already wear several hats, and money not spent on technology appears available for direct work. That makes the trade-off harder to see. The cost remains visible in staff time spent struggling with slow systems, broken integrations, and manual workarounds. Those hours also come out of the mission’s resources.
As needs grow, adding another feature to an old system can seem more defensible than funding a rebuild. The result can become a digital house of cards, slow to use, confusing to navigate, and prone to breaking. Someone still has to hold it together. That person may be a program director or operations lead who inherited technical responsibility. With no clear path out, the organization depends on their troubleshooting while also needing them for the work they were hired to do.
No-code tools can compress the path into this trap. Airtable and similar platforms make it fast to start, but mission-critical processes built without planning for growth can encounter scalability, data ownership, and cost problems. Record limits, pricing walls, and lack of real SQL access become break points. A tool that made a constrained team productive at the start can become difficult to leave once essential work depends on it.
The nonprofit version is therefore not a failure of commitment or judgment. Mission-first decisions can make the hidden costs of technical debt especially difficult to acknowledge. Escaping the dependency requires spending that competes with visible program needs, while staying in it consumes less visible staff capacity. Nonprofits face the same structural problem as a startup, but the room to absorb it is smaller.
The honest objection: the technical founder does have genuine GTM advantages worth naming
Does separating the roles mean ignoring what makes a technical founder good at selling? It should mean nothing of the sort. When the buyer is technical, a founder who speaks the buyer’s language can earn trust through genuine understanding of the product. In developer-led markets, adoption of the product itself can also become distribution. At the earliest stage, staying close to both engineering and GTM may be the right choice.
A technical founder can build custom enrichment pipelines, automation, and scoring logic that a non-technical founder would need to buy or obtain help to create. Building a system to reach buyers differs from being pulled away from them again and again to fix production.
The case changes when the buyer is a committee-driven enterprise, or when trust and narrative decide the deal. Technical credibility still helps, but it cannot take the place of relationships built over time. Nor does it help much if incidents consume the time needed to use it. Once on-call responsibility displaces the conversations that close deals, an early advantage has become an organizational dependency.
How can a founder keep engineering support after launch without hiring full time?
A durable handoff transfers ongoing responsibility for the engineering function. An ongoing engineering retainer can provide that continuing relationship, with a partner responsible for maintenance and support month to month. But an arrangement alone cannot make an unreadable codebase transferable. Where only the founder can navigate the system safely, refactoring or rebuilding the foundations must precede a durable handoff. The time to address that debt is when real users arrive, before acquisition stalls.
A hire, a tool, and a partner engagement are not equivalent to that transfer. Each can leave the founder as the final authority on every risky change. Can engineering operate without repeatedly returning to the founder’s private knowledge of the product? Delegating work while retaining that dependency changes who performs the task, but not who remains responsible when it becomes difficult.
Outsourcing also introduces risks of its own. Hourly billing can reward delivery speed rather than maintainability, while clients who rarely read the code may not see debt accumulating. When projects change hands, patching can take the place of fixing the foundation. To reduce that risk, partner contracts should make tests, linting, performance budgets, and security scans acceptance criteria. Outcome-based milestones should include maintainability metrics, and part of the payment should be held back until a knowledge-transfer audit passes.
A values-aligned partner should also remain involved after the rebuild, rather than treating launch as the end of responsibility. Getting a product live and keeping it reliable are different standards. So a project engagement that ends when the work is delivered differs from a long-term technical partnership that takes charge of ongoing engineering. For a non-technical founder, the latter provides continuity without requiring them to take default responsibility for resolving technical issues. For a technical founder, it creates a lasting exit from the on-call role.
What to do with the freed attention: building a GTM motion that actually compounds
Leaving on-call work does not by itself lead to a healthy pipeline. The founder still needs a GTM motion built as a system. The founder can then keep working on founder-led sales beneath a product-led or community-led top of funnel. That gives the founder room to learn how interest becomes buying intent and whether they can sell to people beyond the unusually forgiving buyers they know. Outbound can then be layered onto a motion that has shown it can repeat.
Technical support for that motion has a separate role. A GTM engineer owns the systems behind go-to-market, including data, enrichment, scoring, automated sequences, and CRM architecture. That is not the same job as maintaining production. Keeping the distinction clear allows the founder to own strategy, relationships, and closing without also becoming the default builder of every acquisition tool. Otherwise, the freed attention can disappear into another technical workload.
Prospecting can find a rhythm, follow-ups can happen regularly, and early conversations can help the founder decide on positioning next. Acquisition is sequential, so a conversation interrupted by an incident can require a restart.
That does not make the engineering investment easy to justify or the handoff effortless to complete. The company has to commit to refactoring, knowledge transfer, and ongoing support before it can see the full benefit to sales. The founder has to weigh whether the company can keep counting on them to be there for emergencies while asking them to build relationships with customers. Stable engineering gives them a different starting point for the next working day. They can return to the buyer conversation, rather than wait to learn which incident will displace it.